Technology
Starlink Mini 2
By Katherine Langford
Advertisement · Why this ad?
Katherine oversees editorial operations across all six brands. Before joining The Meridan Group, she spent 14 years at the Minneapolis Star Tribune, where she led the metro desk through its digital transformation. She holds a Master's in Journalism from Northwestern's Medill School.
More from Katherine →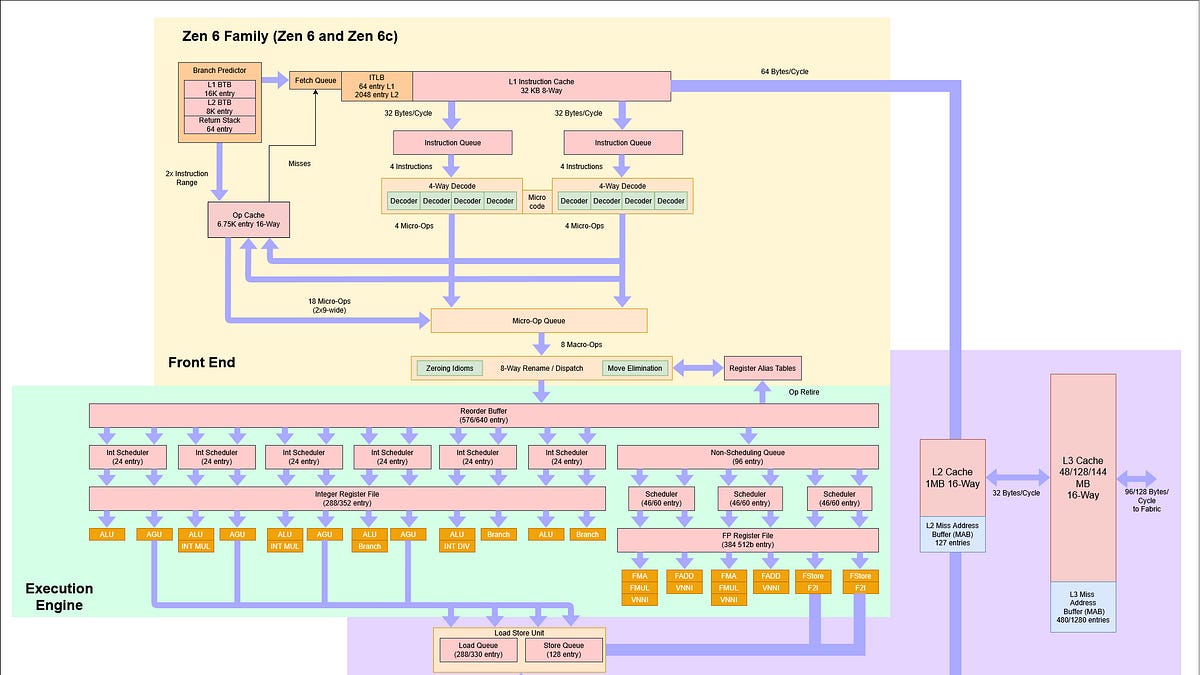
AMD’s Zen 6 Family: Feeding the Beast George Cozma Nov 10, 2026 5 2 Share Hello you fine Internet folks, Today we’re looking at AMD’s next-generation Zen 6 CPU core family. We’ll explore the changes from Zen 5 and what the differences between Zen 6 and Zen 6c tell us about AMD’s approach to microarchitecture. Hope y’all enjoy! Overview From a bird's eye view, Zen 6 is the natural evolution of Zen5, with the expansion of many OoO structures and iterative improvements found throughout the core. Digging in deeper however tells a different story, with AMD heavily re-working several parts of the core, reminding me of the changes from Zen 1 to Zen 2. At a high level the changes AMD made to the integer schedules stand out, returning to a layout reminiscent of Zen 3 and Zen 4. Branch Prediction Zen 5 had the best direction predictor of any core we have measured and Zen 6 seemingly builds upon that same direction predictor. The biggest difference we do see is in what happens once the direction predictor gets overwhelmed. Both cores hit that wall in about the same place and past it, the predictor is left guessing at random data, so the time per branch mostly reflects how long the core takes to recover from a wrong guess. That plateau sits at roughly 3.5 to 4 ns of extra time per branch on Zen 5 and roughly 3 to 3.5 ns on Zen 6 so Zen 6 is paying less for each branch it gets wrong, which speaks to AMD reducing the latency of a branch mispredict compared to Zen 5. Zen 6 has also improved the ability of the core to do 2 branches per cycle with Zen 6 able to do 2 branches per cycle within the L1 instruction cache. When the footprint exceeds the L1i, then it falls to just a single branch per cycle for the rest of the BTB except for the 64B test which goes up to 4 cycles per branch for the L2 BTB. When comparing the BTB of Zen 6 to Zen 5, Zen 6 appears to have focused on improving the speed of the BTB compared to beefing up the capacity. The accuracy of Zen 6’s Branch Predictor Unit is very similar to Zen 5’s while also being faster which is a good thing considering that Zen 5 already had a very accurate Branch Predictor. Instruction Fetch Zen 6 carries forward the same dual decode cluster schema that Zen 5 introduced but, unlike Zen 5 where a single thread could only effectively use a single decode cluster, now with Zen 6 a single thread can use both decode clusters. Outside of the L1i, Zen 6 looks very similar to Zen 5’s behavior on the instruction side of things. Execution Engine The execution engine of Zen 6 is overall very similar to Zen 5, but there are some important differences to be mindful of. On the integer side, Zen 6 brings back Zen 4’s NOP pairing behavior, retiring up to 16 NOPs per cycle. Zen 6 also comes closer to theoretical peak throughput for simple integer instructions than Zen 5, sustaining 5.96 64-bit adds per cycle against Zen 5’s 5.25 with the same six ALUs. AMD has reduced the number of integer multiply units from three to two, with PDEP and PEXT throughput also falling from three instructions per cycle to two. According to AMD, Zen 5’s third integer multiply unit did not justify its area cost. On the vector side, the floating-point units are unchanged, with Zen 6 still handling two 512-bit FADDs, FMULs, or FMAs per cycle. The change is in VNNI, where Zen 6 doubles the number of units from two to four and our 512-bit VNNI test goes from 1.99 to 3.88 instructions per cycle, with Zen 6c matching it. VNNI instructions are useful for operations like calculating the inner loop of quantized inference as well as for video codecs using them for video filters as well. Moving over to the other notable change, Zen 5 could already perform four per cycle, but our test shows only two of them could be vector loads, regardless of if they were 256 or 512 bit loads. Zen 6 raises 256-bit loads to four per cycle on both cores while leaving 512-bit loads at two, so both widths now reach the same 128 bytes per cycle which matters because most shipped vector code still targets AVX1/2. The Out of Order Engine: Where Zen 6 and Zen 6c Split In the past the difference between the Classic cores and the Dense cores in terms of the architecture were, for all intents and purposes, functionally identical with the biggest changes being in the number of cores on a CCD and the amount of L3 cache per core. With the Zen 6 family, that has changed. Starting inside of the core, the changes occur after micro-op dispatch and seemingly end after the load queue. The main differences between Zen 6 and Zen 6c lie in the capacities of their out-of-order structures. Several of these structures are larger on Zen 6c, allowing it to keep more work in flight and absorb more latency than Zen 6. The reorder buffer grows from 576 to 640 entries, the integer register file from 288 to 352, the vector scheduler from 138 to 180, and the load queue from 280 to 330. The differences suggest that AMD is specializing the two designs. Zen 6 appears tuned for high frequency, while Zen 6c has more capacity to tolerate comparatively high memory latency. Zen 6 and Zen 6c use 12-core and 32-core CCDs, respectively, but both provide 4 MB of L3 cache per core. That gives the 12-core CCD 48 MB of L3 cache and the 32-core CCD 128 MB. L3 latency has increased from about 47 cycles on Zen 5 to 55 cycles on Zen 6 and 66 cycles on Zen 6c. The larger caches and greater number of mesh stops likely contribute to the increase. In nanoseconds, Zen 6’s higher clock hides most of the increase, at 10.7 ns against 10.3 ns on the Zen 5-based EPYC 9355P, while Zen 6c’s lower clock and larger CCX put it at 16.4 ns. Moving over to bandwidth, we see that Zen 6 fixes Zen 5’s odd L2 bandwidth behavior, where a core pulled only about 42 bytes per cycle across most of the L2’s capacity, in Zen 6 the read path now reliably delivers 64 bytes per cycle. The rest of the cache hierarchy is largely unchanged in bandwidth per cycle. Load/Store Store-to-load forwarding is seemingly unchanged from Zen 5 and is where the behavior of Zen 6 and Zen 6c re-unify. A 32-bit load from the same address as a 64-bit store completes with effectively zero latency which lets Zen 6 handle two dependent store-load pairs per cycle. Loads fully contained within the store complete in 7 cycles regardless of alignment with partial overlaps costing 14 cycles, matching Zen 5. SPEC CPU 2026 Performance The EPYC 9686F is near the top of our estimated single-threaded SPEC CPU 2026 results. It roughly matches the Ryzen 9 9950X3D2, AMD’s highest-end client CPU from the previous generation, in integer rate and beats it in floating-point rate. At a matched 4.1 GHz, the 9686F leads the 9950X3D2 by about 4% in integer and 11% in floating point, despite the X3D part’s much larger L3. The EPYC 9996 is no slouch either. It roughly matches the previous-generation EPYC 9575F in single-threaded performance, despite running at lower clocks and having four times as many cores. It also edges out NVIDIA’s Vera in integer and leads it by about 20% in floating point. The EPYC 9686F leads on almost every subtest and finishes about 18% ahead of the EPYC 9996 in both suites. It scores 6.20 versus 5.25 in integer and 10.6 versus 8.99 in floating point, with some of its largest leads in 714.cpython, 766.femflow, and 772.marian. Against the Zen 5-based EPYC 9575F, the 9996 scores 5.25 versus 5.13 in integer and 8.99 versus 9.01 in floating point while running about 900 MHz slower. The 9996 also edges out the 9686F in 721.gcc and 765.roms, two subtests where the 9686F’s higher clock provides no advantage. Top-down breakdowns of pipeline slots on the two Zen 6 chips show where the 9686F’s lead comes from. The integer-rate profiles look almost identical in core-bound subtests. In 750.sealcrypto, 710.omnetpp, 735.gem5, and 753.ns3, retiring slots account for nearly the same share on both chips, with differences of less than one percentage point. Me